Charts
How Foundry scales
Visual guides for autoscaling, regions, and reliability — the same story we show enterprises evaluating custom AI clouds.
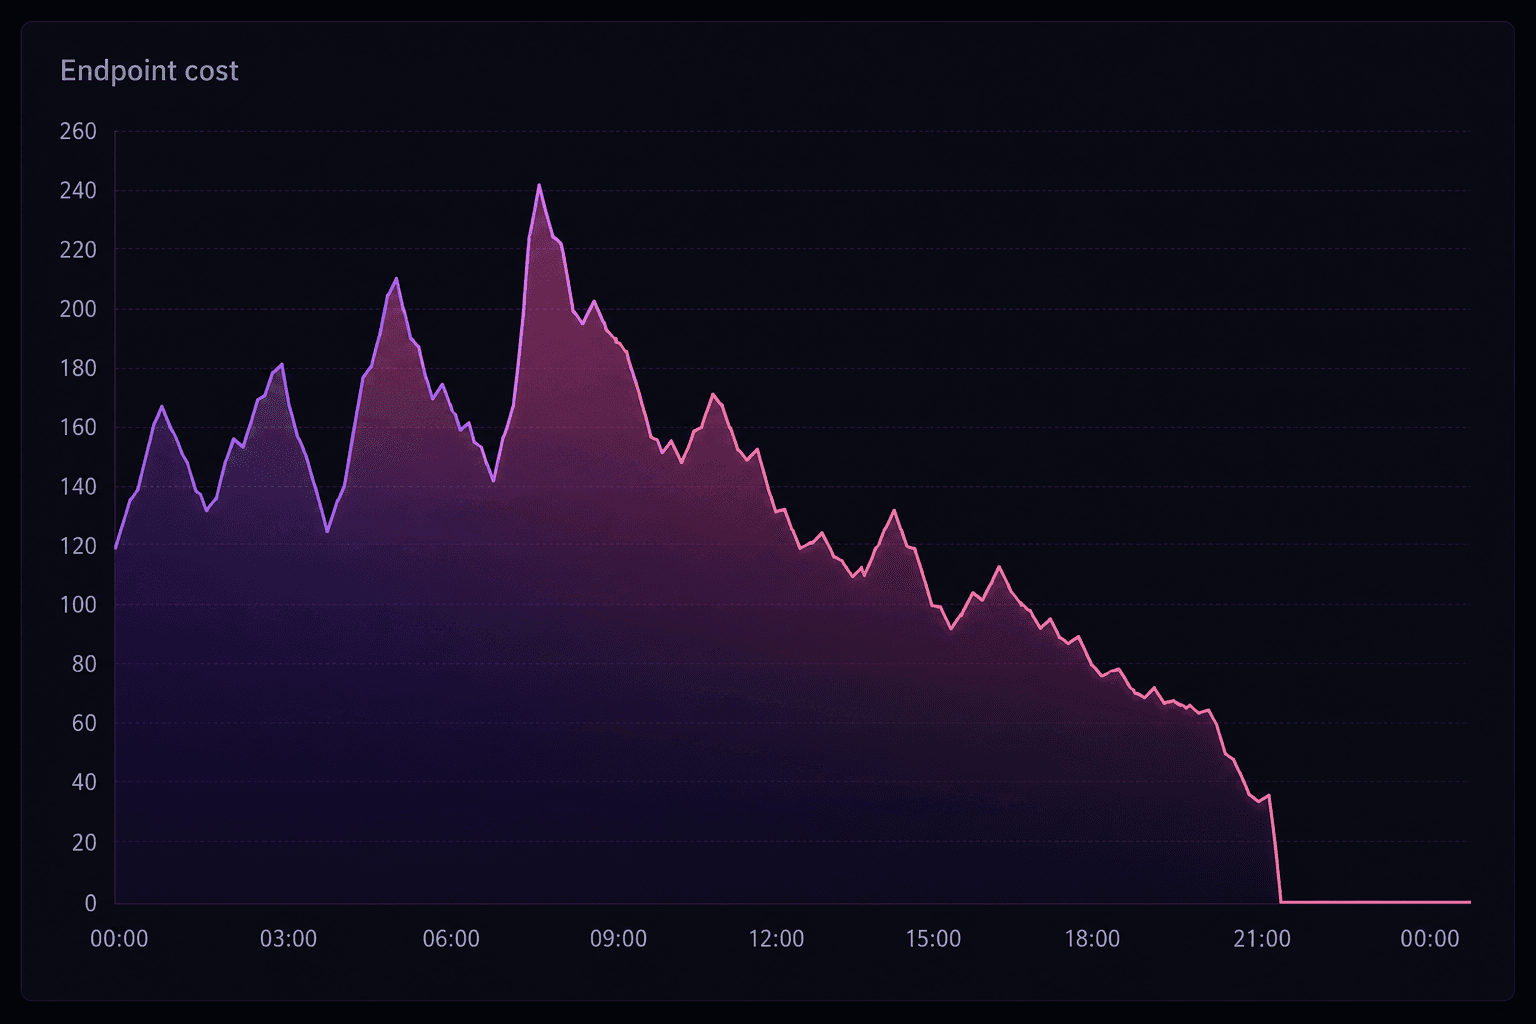
Idle vs busy
Scale to zero when desks are quiet — you don’t pay for idle GPUs.
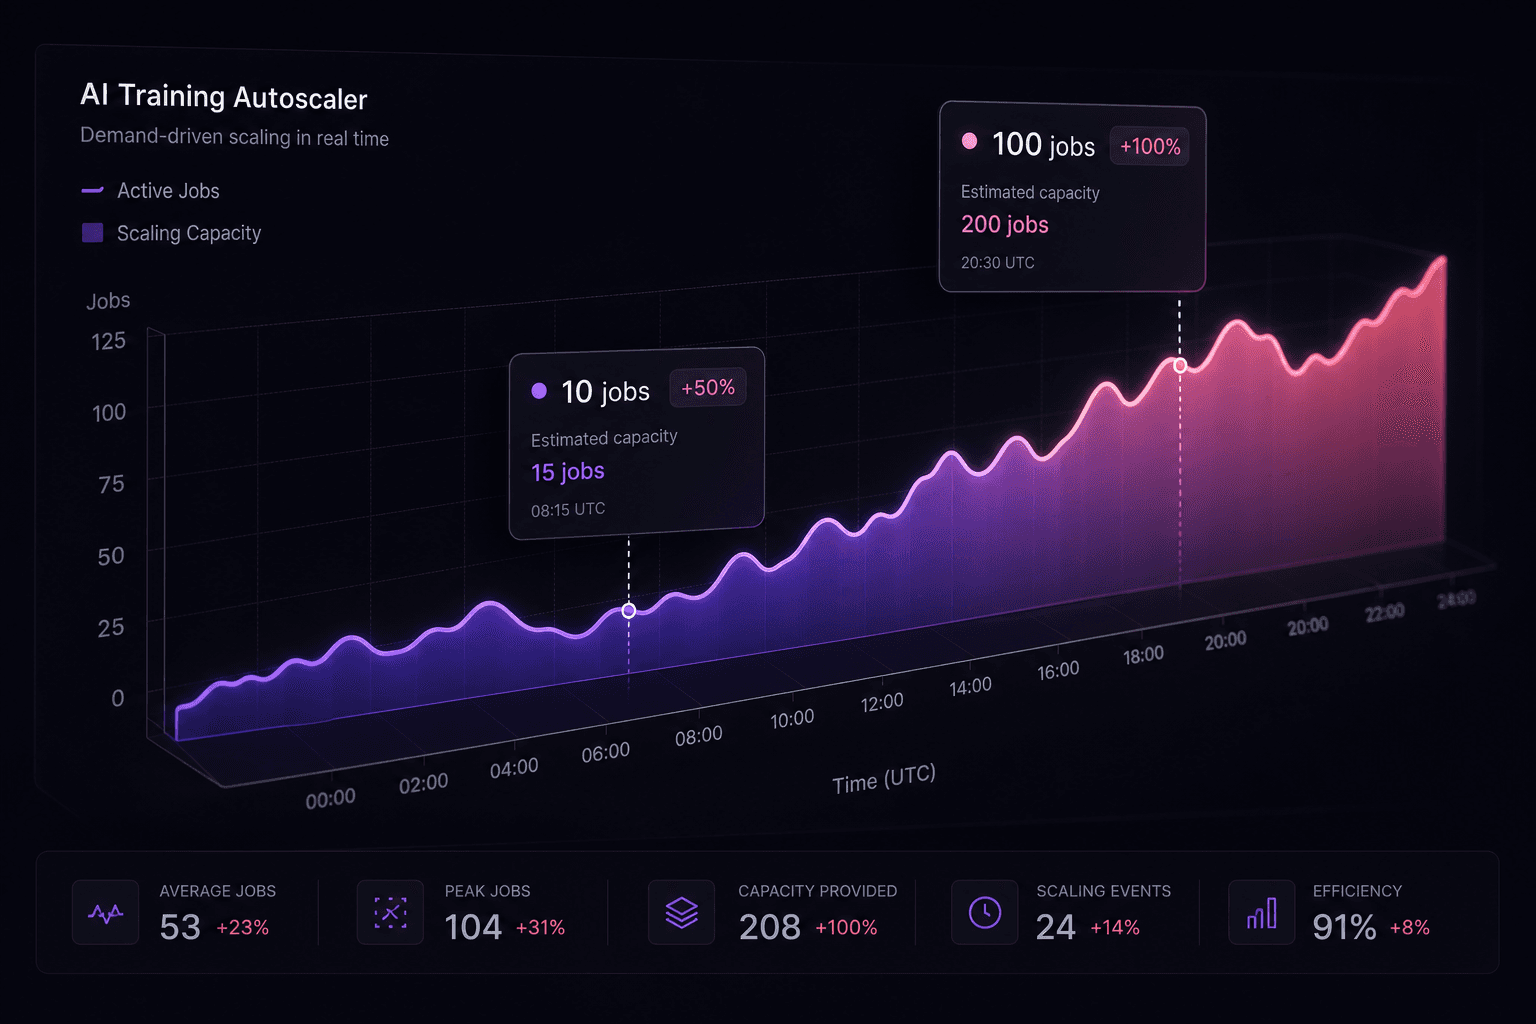
Autoscaling
Traffic spikes spin workers up; traffic drops spin them down.
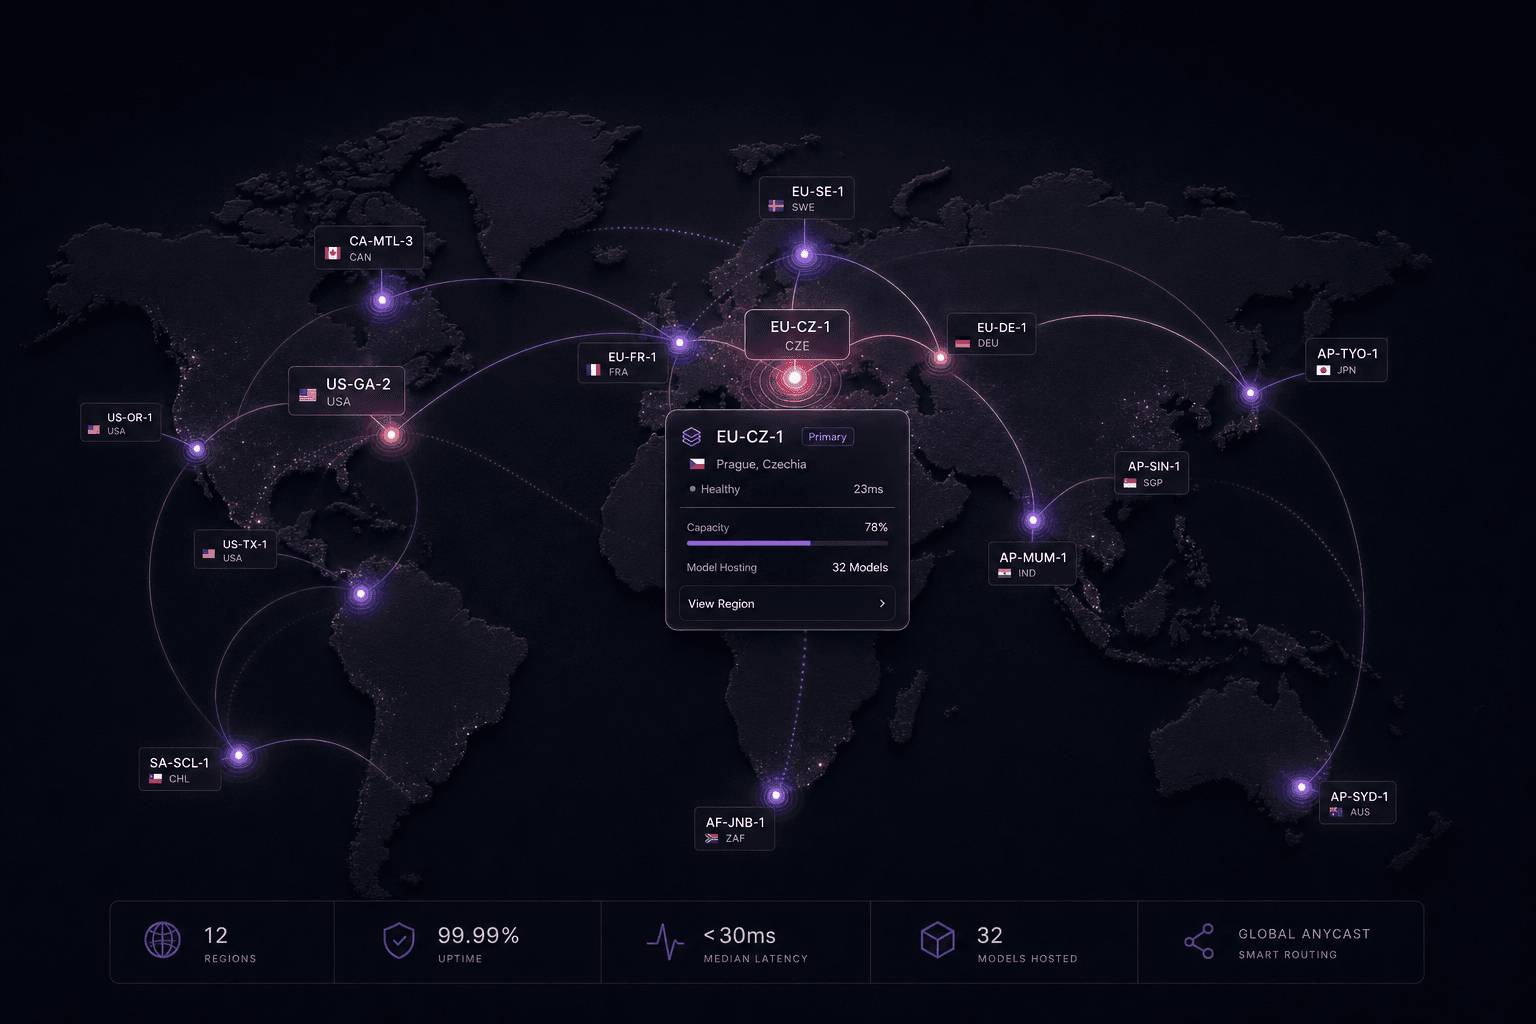
Regions
Place inference closer to your users and data residency needs.
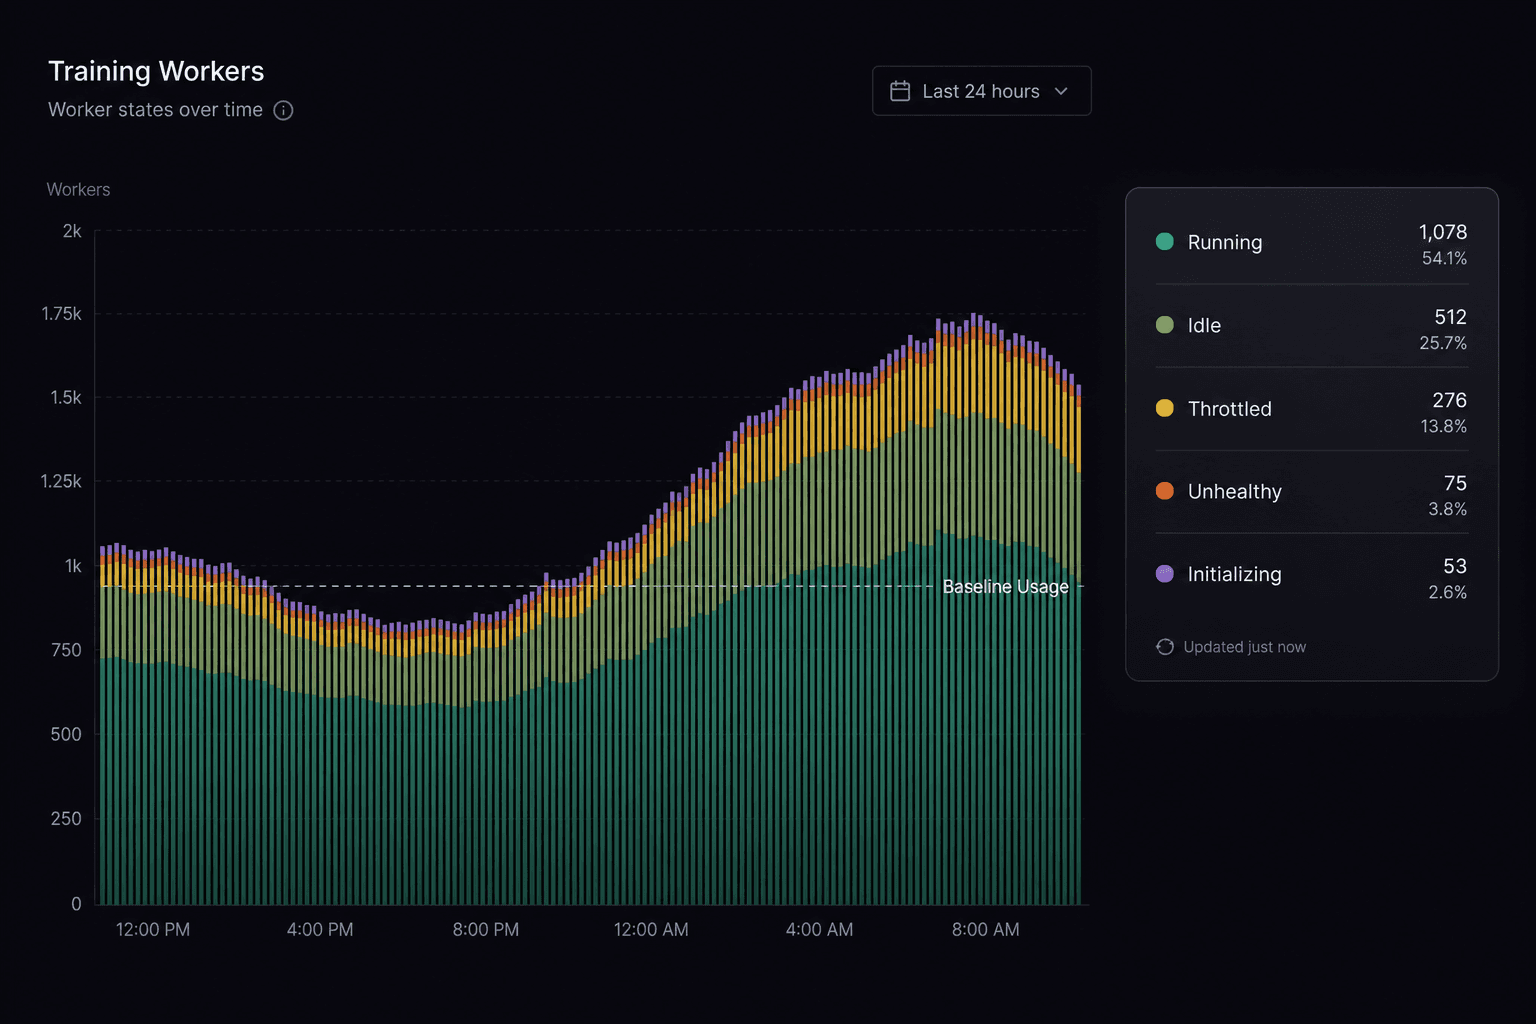
Workers
Parallel jobs for fine-tunes, notebooks, and inference queues.
Reliability
Health checks and retries so training and serving stay online.
Scale
From a single LoRA experiment to many concurrent custom AIs.
Privacy
Your datasets and adapters stay in your account boundary.